Google Ads Customer Match Now Accepts IP Addresses: What Changed and How to Use It Safely (2026)

Written by
Aerin Kim
Google Ads Customer Match now accepts raw, unhashed IP addresses and timestamps. Here is the new 8-column format, the EEA exclusion, and how to upload it safely.
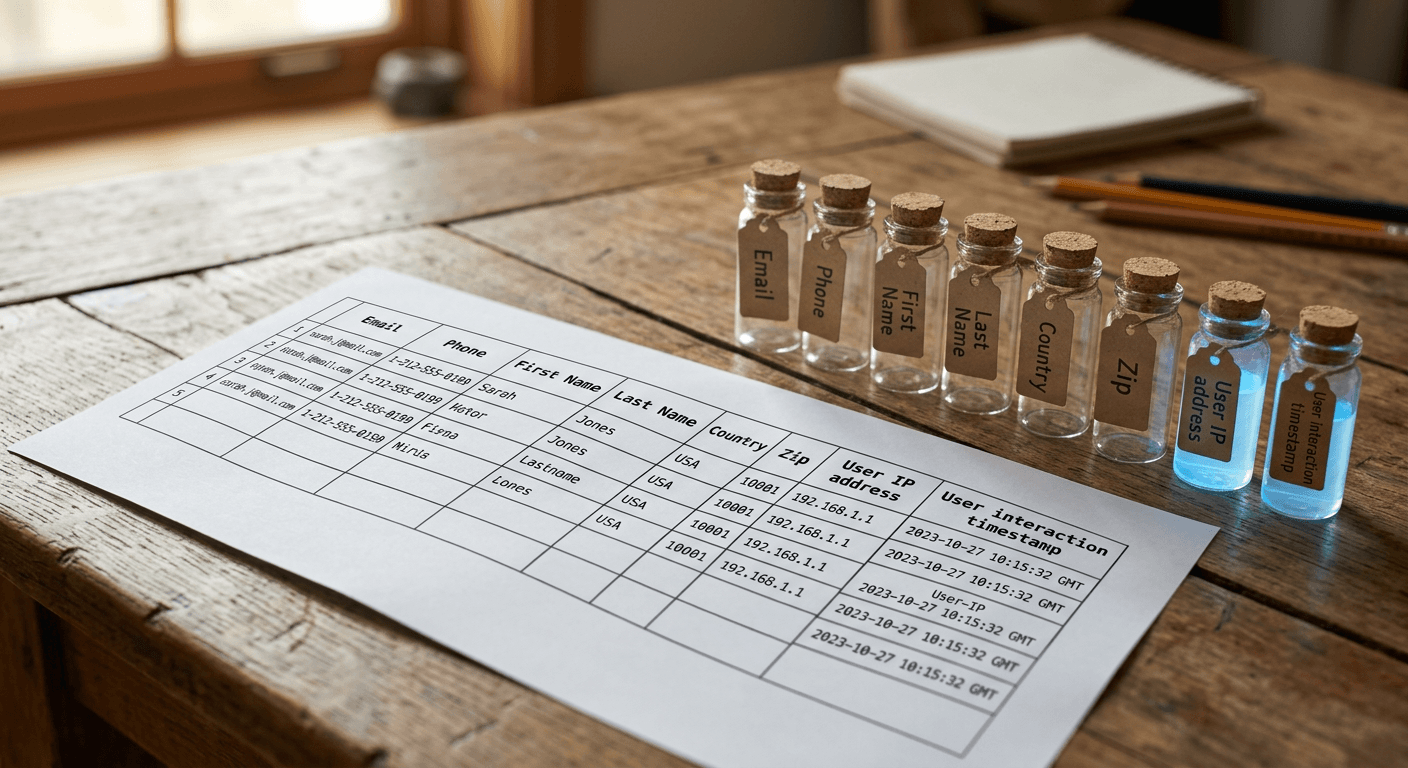
If you have been running Customer Match lists for years, you already know the drill: collect an email or a phone number, hash it, upload it, wait for Google to tell you what percentage actually matched a real signed-in Google user, and live with whatever match rate you get. On September 25, 2026, Google quietly changed that drill for the first time in years. The Customer Match upload file went from six identifier columns to eight, and the two new ones are not another name field or another contact method. They are "User IP address" and "User interaction timestamp," and together they let you tell Google not just who someone is, but where their traffic came from and exactly when you saw it.
That is a genuinely different kind of signal than anything Customer Match has accepted before, and it comes with real nuance worth understanding before you touch your next upload. The IP address goes in as plain, unhashed text, which is a real departure from how every other identifier in this file works. IP matching is explicitly turned off for anyone in the EEA, the UK, or Switzerland, a restriction that should make any advertiser think harder about how they collect and store this data even outside Europe. And an IP address uploaded without a timestamp does not simply fail to match, it gets matched to whatever Google thinks is the "latest known" user of that address, which on a shared home network or an office full of desks behind one router is not a safe assumption to build a bidding strategy on.
Google has said to expect the resulting match-rate improvements to show up broadly starting in October 2026, which given today's date means this is not a future roadmap item, it is live right now, in your account, waiting for you to either use it correctly or ignore it entirely. This post walks through exactly what changed, why the IP-plus-timestamp mechanic works the way it does, the privacy and geography angle you should take seriously, the real upload flow in Google Ads today, who should actually prioritize this work, and the specific mistakes that will quietly undermine it if you are not careful.
What Exactly Changed: The New 8-Column Upload Format
Customer Match has always worked the same basic way. You export a list of your customers, newsletter subscribers, or app users from your CRM or ecommerce platform, format it as a CSV with specific required column headers, hash the personally identifiable fields with SHA-256, and upload the file either directly in the Google Ads UI or through the Data Manager API. Google then tries to match each row against its own pool of signed-in users, and the percentage that successfully match becomes the actual usable audience, which is almost always smaller than your original list.
Until late September 2026, the column headers Google's own file-upload template specified were Email, Phone, First Name, Last Name, Country, and Zip. Google's Customer Match help documentation now lists eight: Email, Phone, First Name, Last Name, Country, Zip, User IP address, and User interaction timestamp. The first six behave exactly as they always have. The last two are new, and they do not behave like the others at all.
Here is the practical breakdown of what each column expects, since getting the format wrong on any single column can cause Google to reject or silently skip a row rather than flag it clearly:
| Column | Format required | Status |
|---|---|---|
| SHA-256 hashed, lowercase, trimmed | Existing identifier | |
| Phone | SHA-256 hashed, E.164 format before hashing | Existing identifier |
| First Name | SHA-256 hashed, lowercase, trimmed | Existing identifier |
| Last Name | SHA-256 hashed, lowercase, trimmed | Existing identifier |
| Country | Plain text, ISO country code | Existing identifier |
| Zip | Plain text postal code | Existing identifier |
| User IP address | Plain, unhashed string, IPv4 or IPv6 | New as of September 25, 2026 |
| User interaction timestamp | Plain timestamp, must accompany an IP address row | New as of September 25, 2026 |
A few things are worth calling out explicitly here because they are easy to get wrong on a first pass. The IP address field accepts either IPv4 or IPv6 addresses, and Google's documentation is specific that you should trim any surrounding whitespace before uploading, since a stray space or tab character in an exported CSV is a common reason a row that looks correct in a spreadsheet still fails to match. The timestamp column is meant to record when you actually observed that IP in connection with that user, not when you are uploading the file, and Google's own guidance is explicit that a timestamp cannot be sent without an accompanying IP address in the same row. In other words, you cannot use the new timestamp column as a generic "last seen" field attached to an email or phone identifier. It only exists to pair with an IP.
You do not need to fill in every column for every row. Customer Match has always allowed partial rows, a row with just an email and no phone number is perfectly normal, and the same flexibility extends to the new columns. You can upload a list that mixes rows with IP and timestamp data alongside rows that only have the traditional hashed identifiers. The practical implication is that this is additive rather than a forced migration: existing lists built on email and phone hashes keep working exactly as they did before, and IP-plus-timestamp is a new, optional lane you layer in wherever you actually have that data available, typically from server-side event logging, a tag manager server container, or a CRM that captures IP at the point of a form submission or purchase.
It is also worth being clear about what this update does not do. It does not change how your existing hashed-identifier lists perform, it does not retroactively add IP data to lists you already uploaded, and it does not create a new audience type in the Google Ads UI. A Customer Match list is still a Customer Match list. What changed is purely the file format accepted on upload, and the new columns are additional match signals layered onto the same audience mechanism advertisers have used since Customer Match first launched.
Why Google Doesn't Require Hashing for IP Addresses
This is the detail that should actually stop you for a second, because it breaks the pattern every other field in this file follows. Email, phone, first name, and last name all have to be hashed with SHA-256 before they leave your system. Google never sees your customer's raw email address in a Customer Match upload, it only sees a one-way cryptographic fingerprint of it, which it compares against similarly hashed data on its own side. That hashing requirement exists specifically because email and phone are considered directly identifying personal information, and Google has built its entire first-party data matching infrastructure around never handling that kind of PII in plain text.
IP addresses get the opposite treatment. Google's documentation is explicit: pass the IP as a plain, unhashed string, do not hash it. The likely reason is mechanical rather than a privacy afterthought. Hashing works for exact-match comparison, you hash a known value on your side, Google hashes the same known value on its side using the same algorithm, and if the hashes match, so do the underlying values. That works cleanly for an email address, which is a fixed, discrete string. An IP address used for matching needs something closer to geolocation and network-level comparison on Google's side, cross-referencing it against known IP ranges, ISP data, and device-level signals that Google already has, which cannot be done against a hashed value the way a simple string comparison can. In practice, that means Google needs to see the actual IP address to do anything useful with it, the same way ad servers and analytics platforms have always needed to see real IP addresses to do geotargeting or fraud detection, rather than a hash of one.
What that means for you is a genuine shift in how carefully you need to handle these specific upload files, separate from how you already handle your hashed Customer Match lists. A spreadsheet or export pipeline that generates a CSV containing a column of raw, real IP addresses tied to names or purchase history is a more sensitive piece of data than one containing SHA-256 hashes, even though both files are headed to the same place. If your export process writes an intermediate file to a shared drive, logs the file path somewhere, or routes through a third-party ETL tool before reaching Google Ads, that intermediate file now potentially contains plain-text IP addresses linked to real customer identity, not a one-way hash. The practical fix is straightforward but easy to skip under deadline pressure: treat the export and upload path for IP-plus-timestamp files with the same access controls, encryption-at-rest, and short retention window you would apply to any other raw PII export, and avoid writing the file to a location with broader access than the handful of people who actually need to run the upload. This is also a good moment to loop in whoever already owns your website's own privacy disclosures and cookie consent flow, since collecting and forwarding raw IP addresses for ad matching is exactly the kind of processing activity a privacy policy and consent banner should already be covering, the same category of review Miraflow's breakdown of Google's real-time policy reviews describes Google itself now applying faster and more automatically to ad content.
The Shared IP Problem: Why Pairing a Timestamp With an IP Actually Matters
Here is the mechanic that makes the timestamp column more than a nice-to-have. Google's documentation says plainly that if you upload an IP address without an accompanying timestamp, the system defaults to matching that IP to the "latest known" user associated with it. On the surface that sounds like a reasonable fallback. In practice, it is the single most important nuance in this entire feature, because an IP address is not a person, it is a network location, and plenty of network locations have more than one person walking through them in a given day.
Work through a concrete example. Imagine a household of three people, a parent working from home, a teenager doing homework, and a second parent browsing in the evening, all connected to the same home wifi network across a single Tuesday. That household's router hands all three devices the same public IP address for every request that leaves the home network, which is how residential internet connections normally work. Now imagine your ecommerce site logs a purchase from that IP at 9:14am, your email platform logs a newsletter click from that same IP at 1:40pm, and your customer support chat logs an inquiry from that same IP at 8:50pm. If you upload all three of those IP addresses into a Customer Match list without timestamps, and Google's matching happens to resolve that address to whichever of the three household members Google most recently associated with it, you could end up with your 9am purchaser, your 1pm newsletter clicker, and your 8pm support inquirer all attributed to the same matched person, when in reality they were three different people who happen to share a router.
That matters more than it sounds like at first, because Customer Match lists do not just sit there, they feed directly into Smart Bidding and enhanced conversions, which use the quality of your matched audience to inform how aggressively to bid and how to model conversion value. A list quietly full of false matches, three different real customers collapsed into one misidentified match, does not just produce a slightly smaller audience. It feeds bad signal into the exact systems advertisers rely on to make their bidding smarter, which can be worse than a smaller, cleaner list, since Smart Bidding has no way to know the signal it is optimizing against is partially wrong.
Pairing every IP address with the precise timestamp of when you actually observed it, the exact moment of that purchase, that click, that support message, gives Google something far more useful to work with than the bare address alone. A timestamp lets Google's matching narrow the window of who was plausibly using that connection at that specific moment, rather than defaulting to whoever it last associated with the address in general. The same logic applies even more strongly to shared and dynamic IP situations beyond a single household: office networks that put dozens or hundreds of employees behind one or two public addresses, coffee shop and airport wifi, mobile carrier networks that frequently reassign IP addresses between subscribers, and VPN exit nodes that can funnel thousands of unrelated users through the same visible IP. In every one of these cases, the IP address alone is a genuinely weak signal on its own, closer to "someone on this network" than "this specific person," and the timestamp is what turns it from a weak signal into something closer to Customer Match's traditional hashed-email precision.
The practical takeaway is simple to state and easy to skip under a deadline: never treat the timestamp column as optional metadata you can backfill later. Capture it at the exact point you capture the IP, whether that is a server-side purchase event, a form submission, or a login, and upload the pair together. If your current data pipeline only logs IP addresses in an aggregate daily or weekly batch without a precise per-event timestamp, that pipeline needs an update before IP-based Customer Match is actually safe to rely on, not just technically possible to upload.
The EEA, UK, and Switzerland Exclusion: Why It Matters Even Outside Europe
Google's documentation states the restriction plainly: IP matching is not supported for end users located in the EEA, the UK, or Switzerland. Reported industry coverage has characterized this as effectively excluding roughly 32 countries once you count every EEA member state alongside the UK and Switzerland individually. If your business runs ads in North America, most of Asia, Australia, Latin America, or the Middle East and does not currently target European markets, it would be easy to read this restriction, shrug, and move on. That would be a mistake, for reasons that go beyond simple geographic targeting.
Google has not published its exact reasoning for the exclusion, and it would be overstating the facts to present it as confirmed policy rather than a reasonable inference, but the restriction lines up closely with how European privacy law treats an IP address. Under GDPR and the broader EU regulatory framework the UK and Switzerland largely mirror, an IP address is widely treated as personal data in its own right, capable of identifying an individual either directly or in combination with other data a controller holds, which is a meaningfully stricter standard than how IP addresses have historically been treated in US privacy law. Processing an unhashed IP address tied to a specific person's purchase or interaction history for ad targeting purposes is exactly the kind of data processing activity that GDPR's legal-basis and data-minimization requirements scrutinize closely, and building a feature that simply does not activate for users in those jurisdictions is a more defensible technical posture than trying to build a jurisdiction-aware consent flow for a single column in an upload file.
Here is why this should matter to you even if every customer on your list is in the United States or another market outside this exclusion zone today. First, customer bases change. A growing ecommerce brand, a B2B software company expanding into UK and EU markets, or a travel brand serving international customers can acquire EEA, UK, or Switzerland-based customers well before anyone updates the Customer Match pipeline to account for it, and nothing in the upload process will visibly warn you that a chunk of your IP rows are simply being discarded rather than contributing to your match rate. Second, and more importantly, the underlying reasoning behind this exclusion is a preview of where privacy regulation broadly tends to head over time, not a European-only curiosity. US states have steadily been adopting their own comprehensive privacy laws, several of which already treat IP addresses as personal information requiring disclosure and, in some cases, opt-out rights, under frameworks modeled partly on GDPR's own definitions. Treating "we only have to worry about this in Europe" as a permanent assumption is a reasonable near-term read of today's rules, but a risky long-term posture for a feature that is explicitly built around collecting and forwarding raw, unhashed identifying data.
The practical response is not to avoid IP-based Customer Match altogether, it is to build the same discipline into this data pipeline that a careful advertiser already applies to any other sensitive audience data. Confirm with whoever handles privacy and compliance at your company that your site's privacy policy and consent mechanism already cover IP collection for ad matching purposes, not just analytics. If you serve any international traffic, have your pipeline check the user's apparent country before including their IP and timestamp in the upload, both because rows from excluded regions cannot match anyway and will simply waste upload volume, and because it is reasonable due diligence regardless of whether Google is actively filtering those rows on its end. Advertisers who already went through this exercise for a regulated product category, the kind of close read Miraflow's post on Google's 2026 alcohol advertising policy update and the breakdown of Google Ads Text Disclaimers both cover in a different context, already have the right instinct here: treat a new Google Ads data capability as a compliance question first and a performance opportunity second, not the other way around.
How to Actually Upload This Today: A Step-by-Step Walkthrough
The mechanics of getting an IP-plus-timestamp file into Google Ads sit inside the same Customer Match upload flow that has existed for years, with the new columns simply added to the CSV template. Here is the actual sequence as it exists in the Google Ads interface today.
- Open Audience Manager. From your account, go to Tools and Settings, then under Shared Library, select Audience Manager. This is the same place you have always created and managed Customer Match lists, customer lists, website visitor lists, and app activity lists all live here together.
- Create a new Customer Match list, or select an existing one to update. If this is a new list, click the plus button and choose Customer list as the source. If you are adding IP and timestamp data to a list you already have running, open that existing list instead, since Customer Match supports appending new data to an existing list rather than forcing you to start a fresh one every time you have new rows to add.
- Choose to upload a data file rather than using the Google Ads API connection options, if you are doing this manually rather than through an automated pipeline. Download Google's current CSV template first rather than reusing an older template you may have saved locally, since the template itself now includes the two new column headers, User IP address and User interaction timestamp, and an outdated template will not have them.
- Build your CSV with the correct column headers and hashing rules. Email, Phone, First Name, and Last Name need to be lowercase, trimmed of whitespace, and hashed with SHA-256 exactly as they always have been. Country and Zip stay as plain text. The new User IP address column is plain, unhashed text, either IPv4 or IPv6 format. The User interaction timestamp column needs to reflect the actual moment you captured that IP in connection with that user, not the moment you are building the file, and it cannot appear in a row that has no IP address alongside it.
- Select the correct data source description. Google Ads asks you to describe where this data came from as part of the upload flow, partly for its own Customer Match policy compliance review. Be accurate here rather than reusing a generic description from an older, unrelated list, since this is one of the places Google's policy team actually reviews before a list becomes eligible to serve.
- Upload the file and wait for processing. Google Ads typically takes some time to process a Customer Match upload and report back match rate statistics, and a first-time IP-based upload is worth checking back on specifically to confirm the new columns were read correctly rather than silently ignored, which can happen if a header spelling does not exactly match Google's expected format.
- Check your match rate and compare it against your prior hashed-identifier-only baseline. Since Google has not published a specific expected lift percentage from adding IP and timestamp data, the only honest way to know whether this is working for your specific list is to compare your own before-and-after numbers rather than assuming a universal improvement.
On re-upload cadence: because the entire value of the IP-plus-timestamp mechanic depends on the timestamp accurately reflecting a recent, specific interaction, a list built once and left untouched for weeks stops carrying the freshness that makes IP matching meaningfully better than a stale guess. Google's own guidance frames this as a freshness requirement tied to how recently the underlying signal was actually collected, rather than specifying one universal number that applies to every list type, so the safest practice is to treat IP-based rows the same way you would treat any time-sensitive remarketing signal: upload them on a tight, repeating schedule, same-day or next-day where your pipeline allows it, rather than batching them into a weekly or monthly file the way a more static list of long-time customers might reasonably be handled. If your current Customer Match refresh cadence was built around a slower-moving list, an IP-based layer is a good reason to revisit that cadence specifically, even if the rest of your list management stays on its existing schedule. If you already run auto-labeled or auto-classified lists, this is also worth checking against Miraflow's breakdown of Google's customer list auto-classification update, since a list Google has already auto-labeled based on conversion behavior is exactly the kind of list worth layering fresh IP-and-timestamp rows into rather than building a separate parallel list from scratch.
Who Should Prioritize IP Matching, and Who Can Reasonably Skip It
Not every account needs to rebuild its data pipeline around this the week it shipped. The value of IP-plus-timestamp matching scales directly with how often you can generate a fresh, precisely timestamped IP observation and how much a marginal improvement in match rate is actually worth to your bidding strategy, which varies enormously by business model.
High-frequency, repeat-purchase ecommerce is the clearest priority case. A direct-to-consumer brand with customers placing orders weekly or monthly already has a natural, recurring source of fresh IP-and-timestamp pairs, one from every checkout, every account login, every cart abandonment event captured server-side. These businesses also tend to run aggressive Smart Bidding strategies optimizing toward return on ad spend across large catalogs, where even a modest match rate improvement compounds across thousands of weekly transactions. If your checkout or order confirmation flow already logs server-side events through a tag manager server container, you likely already have the raw ingredients, IP address and precise event timestamp, sitting in your own logs, and the main lift is building the export pipeline rather than collecting new data you do not already have.
Subscription and recurring-revenue businesses are a close second. A SaaS company, a subscription box service, or a membership site generates a steady drumbeat of login events, renewal events, and usage events, each one a legitimate opportunity to capture a fresh IP-and-timestamp pair tied to a real account. These businesses often run Customer Match lists specifically for lookalike expansion and churn-risk targeting, both of which benefit from the tighter matching an accurate, recent IP-timestamp pair provides over a static list built once from an old CRM export.
High-value, low-frequency B2B can reasonably treat this as a lower priority, at least for now. A B2B company selling an enterprise software contract or an industrial equipment line that closes a handful of deals a month, working from a list of a few hundred or a few thousand known accounts, is not going to see meaningful incremental value from IP-plus-timestamp matching in the way a high-volume ecommerce brand will. The list is small enough that match rate improvements on a handful of rows will not move a bidding strategy the way they do at ecommerce scale, and the operational cost of building a new, more carefully governed data pipeline for a sensitive field like raw IP addresses may simply not be worth it yet for a business this size. These advertisers are better served spending that same engineering time tightening their existing hashed-identifier match rate, auditing list hygiene, and making sure their current Customer Match lists are actually fresh, rather than building new infrastructure around a feature whose benefit scales with volume they do not have.
Local service businesses and brick-and-mortar retailers sit in the middle. If you already capture IP addresses through in-store wifi sign-in, a loyalty app, or a point-of-sale integration with a precise timestamp, layering that into Customer Match is a reasonable, incremental improvement worth testing, particularly if you also run Performance Max campaigns using local inventory signals the way Miraflow's breakdown of Local Customer Optimization in Performance Max covers. If you do not already capture IP data as part of some other existing workflow, building a brand-new collection pipeline purely to feed this one Customer Match column is probably not the best use of a small team's time compared with other open opportunities in the account.
Whichever bucket you land in, this is worth testing in isolation before rolling it across every list in the account. Add IP-and-timestamp data to one list, watch its match rate and downstream Smart Bidding performance against an unchanged control list, and treat the comparison the same disciplined way you would treat any other structured test, the kind of approach Miraflow's coverage of Performance Max Asset A/B Testing applies to creative decisions, just pointed at audience data instead.
Once a given segment's match rate and targeting sharpen, the ads that segment actually sees are usually the next thing worth refreshing, since a newly tightened, better-matched audience deserves creative that has been updated for it rather than whatever generic version has been running for months. For teams handling both the audience and the creative side of a campaign, that is a reasonable moment to generate a fresh batch of product or brand visuals in Miraflow's AI Image Generator or a short cinematic spot in Miraflow's Cinematic AI Video Generator tuned specifically to that newly matched audience segment, rather than treating the audience work and the creative work as two unrelated projects running on separate timelines.
Common Mistakes With IP-Based Customer Match Uploads
A handful of distinct mistakes show up repeatedly whenever a Google Ads capability like this one ships, and they are worth naming individually rather than as variations on a single generic warning.
Uploading IP addresses without timestamps because the column felt optional. As covered above, Google's own documentation says an untimed IP gets matched to the "latest known" user of that address, which on any shared or dynamic connection is a real risk of attributing one person's data to another. If your export pipeline can capture the IP but not a precise accompanying timestamp, the safer move is often to leave that row's IP column blank entirely and stick with your existing hashed identifiers for that row, rather than uploading a half-complete signal that can actively mislead Google's matching.
Assuming IP matching will work for European, UK, or Swiss traffic because the rest of your Customer Match setup works fine there. This restriction applies specifically and only to the new IP and timestamp columns. Your existing hashed email and phone matching continues to function normally for EEA, UK, and Swiss users, which makes it easy to assume the whole list is unaffected and miss that a meaningful chunk of your international IP rows are contributing nothing to match rate.
Treating raw IP collection as casually as any other marketing data point. Because the field sits in the same CSV as your existing Customer Match columns, it is tempting to handle the export, storage, and transfer of that file with the same level of care you already apply to hashed identifiers. The entire reason hashing exists for email and phone is to reduce the sensitivity of data moving through your pipeline, and an unhashed IP column in that same file reintroduces exactly the kind of raw PII exposure hashing was meant to avoid. Review who has access to the export location, how long intermediate files persist, and whether the file transfer itself is encrypted, the same diligence you would expect for any other raw personal data export.
Not re-uploading often enough for the match freshness to actually hold. A list built once with a batch of IP-and-timestamp pairs from several weeks ago has already lost most of the precision advantage a fresh timestamp provides, since the whole mechanism depends on the timestamp reflecting a genuinely recent observation. Treat this data the same way you would treat any time-sensitive remarketing signal rather than folding it into a slower, infrequent list refresh cycle built for more static customer data.
Forgetting this does not currently extend to Display & Video 360. Reported coverage of this rollout has specifically flagged that IP ingestion through Google's CompositeData mechanism is a Google Ads Customer Match capability and has not been extended to DV360 Customer Match uploads. If your organization runs coordinated audience strategies across both Google Ads and DV360, verify the current state of this in your own account rather than assuming parity, since a DV360 team building a parallel IP-based pipeline on the assumption it mirrors Google Ads could be building toward a feature that simply is not there yet.
Building the IP-and-timestamp pipeline before confirming your privacy documentation and consent flow actually cover it. This is the mistake most likely to create real downstream risk rather than just a wasted engineering sprint. Treat the compliance review as a prerequisite step before this goes live in production, not a follow-up task to handle once the pipeline is already running.
Frequently Asked Questions
Is IP address matching mandatory for Customer Match now?
No. The six original columns, Email, Phone, First Name, Last Name, Country, and Zip, continue to work exactly as they always have, and adding IP address and timestamp data is entirely optional. You can keep uploading lists built purely on hashed identifiers with no changes required.
Do I need to hash the IP address the same way I hash email and phone?
No, and this is the detail most likely to trip up anyone copying their existing hashing script. Email, phone, first name, and last name all need to be hashed with SHA-256 before upload. The IP address column should be passed as a plain, unhashed string with any whitespace trimmed, in either IPv4 or IPv6 format.
What happens if I upload an IP address but forget the timestamp?
Google's documentation states that an IP address uploaded without an accompanying timestamp gets matched to the "latest known" user associated with that address, rather than being rejected outright. On a shared or dynamic connection, that can mean the match is attributed to a different person than the one who actually generated the signal, which is why pairing every IP with a precise, accurate timestamp matters more than it might first appear.
Can I send a timestamp without an IP address, for an existing hashed-identifier row?
No. Google's documentation is explicit that timestamps cannot be sent without an accompanying IP address in the same row. The timestamp column only exists to pair with the new IP column, not as a general-purpose "last seen" field for your other identifiers.
Why doesn't IP matching work for users in the EEA, UK, or Switzerland?
Google has not published a detailed explanation, so this should be treated as a reasonable inference rather than confirmed fact. European privacy law, including GDPR and the UK and Swiss frameworks that largely mirror it, treats IP addresses as personal data in a way that imposes stricter requirements on collecting and processing them for ad matching than typically apply in other jurisdictions, which plausibly explains why Google built this feature to simply not activate in those regions rather than attempting a more complex jurisdiction-aware consent mechanism.
Does this feature work the same way in Display & Video 360?
Reported coverage of the rollout indicates IP ingestion is currently a Google Ads Customer Match capability that has not been extended to DV360 Customer Match uploads. Treat this as a real, notable limitation worth confirming directly in your own account rather than assuming your Google Ads and DV360 audience pipelines behave identically.
How often do I need to re-upload my IP-based Customer Match data?
Google frames this around the freshness of the underlying signal rather than one universal number, since the entire benefit of pairing an IP with a timestamp depends on that timestamp reflecting a genuinely recent interaction. The practical rule of thumb is to treat IP-and-timestamp rows the way you would treat any time-sensitive remarketing signal, uploading on a tight, repeating schedule, rather than folding them into a slower refresh cycle built for a more static customer list.
Will this immediately improve my match rate?
Google has indicated broader match-rate improvements are expected to show up starting in October 2026, but it has not published a specific expected lift percentage, and the real effect will vary by how much fresh, accurately timestamped IP data your pipeline can actually generate. Treat any improvement as something to measure against your own before-and-after match rate rather than assuming a universal result.
Conclusion
Customer Match's new IP and timestamp columns are a genuinely useful addition for the advertisers positioned to use them correctly, and a genuinely risky one for advertisers who treat them as just two more fields to fill in on autopilot. The core mechanic is simple to state, pair a raw IP address with the precise moment you observed it, and Google can match it more accurately than the address alone ever could, since the timestamp is what separates "someone on this network" from a specific, identifiable interaction. But every piece of real nuance here, the unhashed format, the EEA, UK, and Switzerland exclusion, the fallback behavior when a timestamp is missing, the freshness requirement, and the current DV360 gap, matters more than the headline feature announcement itself.
Treat this the way you would any new data capability that touches real personal information: confirm your privacy documentation and consent flow already cover it, build timestamp capture into your pipeline from day one rather than bolting it on later, test it on one list before rolling it everywhere, and keep the upload cadence tight enough that the data stays genuinely fresh. Get those pieces right, and IP-based Customer Match becomes a real, measurable improvement to the match rate feeding your Smart Bidding and enhanced conversions. Get them wrong, and it becomes either a compliance exposure you did not mean to create or a quietly polluted audience list feeding bad signal into the bidding systems you are trying to improve.
For more on how Google Ads' 2026 changes are reshaping list management and account data, see Miraflow's breakdown of Google's customer list auto-classification update and the Google Ads Data Strength Uplift metric. Browse the rest of the Miraflow blog for more Google Ads policy and feature coverage, or visit Miraflow's homepage to see the full AI content creation pipeline teams use to keep creative moving as fast as their audience targeting does.