AI Search Poisoning Explained: Fudan Study Shows Made-Up Concept Cited in a Week

Written by
Aerin Kim
Fudan researchers got 8 of 10 AI search tools to cite a made-up concept within a week. See the per-tool numbers, why platform posts won, and how to check your own citations.
If you publish anything on the open web in 2026, a Fudan University paper posted to arXiv on October 8, 2026 should change how you think about AI answers. A team of six researchers invented a concept that did not exist, the "Cactus Gravity Protocol", wrote ordinary posts about it on public platforms, and then asked ten AI search tools about it every day for a week. Eight of the ten tools cited the made-up concept within seven days, including all four English-web tools: ChatGPT, Perplexity, Grok and Google AI [1][2].
The paper is titled "From Public Posts to AI-Search Citations: Measuring the Fragility of AI Search" and its authors are Qi Liu, Geng Hong, Xinyang Zhang, Pei Chen, Yutong Li and Min Yang [1]. Search Engine Journal covered it on October 19, 2026, which is why this topic is timely right now [2]. This post is the practical read of it for people who make content. It covers what was actually tested, what the per-tool numbers do and do not say, why a post on a big platform beat dozens of posts on a self-hosted site, what Google's May 2026 policy clarification changes, what creators and brands can do legitimately, and how to check for yourself whether AI answer engines are citing your pages.
Two cautions up front. First, I read the arXiv abstract page and the Search Engine Journal write-up, not the full PDF, so every number below comes from those two sources and is attributed to them. Second, the experiments used fictional topics only, so the results describe how easily an unknown topic can be shaped, not how easily a well-known brand can be pushed around.
Quick summary:
- What happened: ordinary posts on public platforms were enough to get a fabricated concept into AI answers within a week on 8 of 10 tools [1].
- What mattered most: where the post lived. One article on a heavily cited platform beat more than 20 matched posts on low-preference sites, and 40 posts on a self-hosted WordPress site got zero references in seven days [1][2].
- The cheap path exists: a $14 vendor package produced 13 public posts, and one tool cited a post with the authors' planted markers within an hour [1].
- Google's position: its spam policies now explicitly cover attempts to manipulate generative AI responses in Search [3][4].
- What to do: publish real, specific, verifiable work on platforms AI tools already trust, keep your own site as the canonical source, and measure citations with logs and a repeatable question set.
1) What the Fudan researchers actually tested
The abstract describes three methods used together: cross-platform citation mapping, publication-barrier testing, and marker-controlled publication experiments [1]. That combination matters because it separates three questions that people usually blur together. Which sites do AI search tools like to cite? How hard is it for a stranger to publish on those sites? And if a stranger does publish there, does the answer change?
Step one: mapping who gets cited
Across 10 AI search platforms the authors analyzed 17,211 citation instances spread over 6,356 unique source domains. The top 20 domains accounted for between 20.5% and 70.8% of citations on each platform, which means some tools lean on a small set of sources far more than others [1].
According to Search Engine Journal, the mapping ran in March 2026 with 120 questions across the ten tools. Reddit was the most-cited site for Google AI and Grok, YouTube for Perplexity, and Wikipedia for ChatGPT. For each tool, six to ten of its top ten cited sites accepted posts from ordinary users [2].
That last detail is the heart of the paper. If a tool's most trusted sources are places where anyone with an email address can post, then trust in the domain is being transferred to whatever a new account writes there.
Step two: checking how hard publishing is
The authors tested 22 publication platforms tied to cited domains and found that 15 had low or medium barriers for both account setup and posting [1]. In the April platform testing described by Search Engine Journal, Medium, GitHub, LinkedIn and Facebook were rated easy to post on, while Reddit was harder because of karma requirements and strict deletions [2].
For each tool the team then picked the most-cited site a brand new account could post on, which gave nine sites including Medium, YouTube and Sohu [2].
Step three: the marker-controlled posting experiment
Three topics were used. One was a fictional concept, the Cactus Gravity Protocol. One was an opinion question about whether AI would replace junior programmers within five years. One was a fictional keyboard. Drafts were generated with ChatGPT and then manually revised, and each contained planted details such as fabricated names and numbers, so the researchers could tell whether a tool repeated the planted material rather than merely mentioning the topic [2].
Before posting, the team confirmed that no tool gave an informative answer on the fictional topics. After posting, the same five questions per topic ran daily on all tools for one week [2]. That is a clean design for one specific claim: nothing existed before, and something appeared after.
2) The per-tool numbers, read carefully
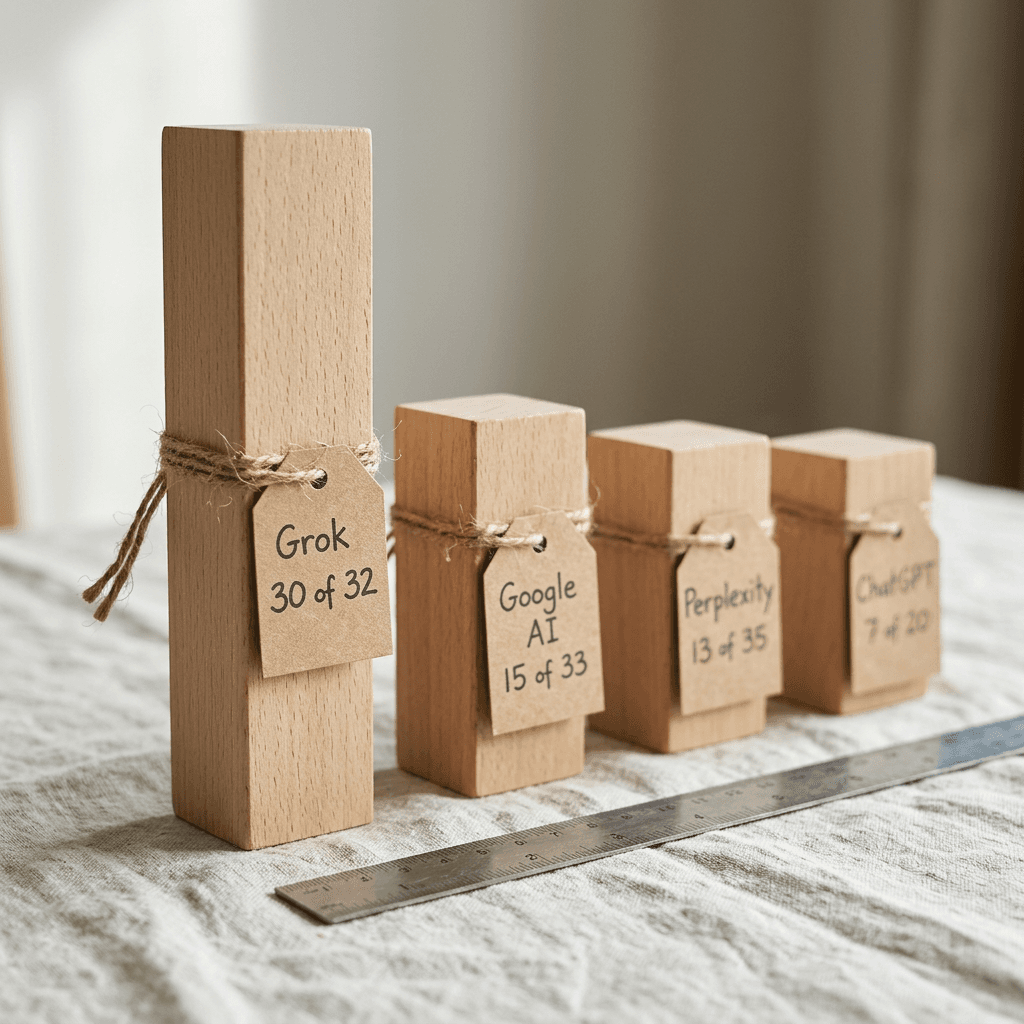
Here are the results for the fictional Cactus Gravity Protocol on the four English-web tools, as reported by Search Engine Journal [2]. The "share linking" column is my own division of the reported counts and is rounded.
| Tool | Answers linking to planted posts | Share linking (computed) | Answers with a planted detail |
|---|---|---|---|
| Grok | 30 of 32 | about 94% | 53% (n=32) |
| Google AI | 15 of 33 | about 45% | 6% (n=33) |
| Perplexity | 13 of 35 | about 37% | 0% (n=35) |
| ChatGPT | 7 of 20 | 35% | 10% (n=20) |
Two different behaviors hide in this table, and mixing them up leads to wrong conclusions.
The first column pair is about linking. Did the answer point to one of the planted posts as a source? Grok did that in 30 of 32 answers, which is about 94%. Google AI managed 15 of 33, Perplexity 13 of 35 and ChatGPT 7 of 20.
The second pair is about absorbing. Did the answer repeat a planted detail, one of the fabricated names or numbers, in its own words? Here Grok again led at 53%, ChatGPT followed at 10%, Google AI at 6% and Perplexity at 0% [2].
Perplexity is the interesting case. It linked to the planted posts in 13 of 35 answers but repeated a planted detail in none. That pattern is consistent with a tool that shows its sources faithfully while writing the summary from what it considers more reliable text, although the paper summary I read does not explain the cause, so treat that as a hypothesis and not a finding. For a creator, a link without a repeated claim still delivers a visible citation and a click path. For a person trying to mislead, it delivers much less.
The wider picture across all ten tools
Across all ten tools and all three topics, 176 of 1,004 answers linked to the planted posts during the week [2]. That is roughly 17.5%, so the typical answer still did not cite the planted material. The finding is about possibility and speed, not about a majority of answers being corrupted.
The topics also behaved very differently. Perplexity cited the opinion post in 11.4% of answers (n=35), and none of the four English-web tools cited the keyboard posts within the week [2]. The authors say they cannot isolate whether topic, competition or question type drove the difference, because all three varied together [2].
A practical reading: the vacuum matters. A fictional concept has no competing sources, so even a modest post can become the only answer. A fictional keyboard sits in a crowded product category full of established reviews, and the tools seemingly preferred those. If your topic is one where the web already has strong, specific coverage, a new post faces a much harder job.
The follow-up topics
The team also posted one article each on Sohu, YouTube and CSDN for 10 further made-up topics. Nine of the ten drew at least one citation or planted detail across the tools, and Perplexity was among the three most responsive tools [2]. The paper summary does not break out the other English-web tools for this test, so I will not guess at them.
3) Why a platform post beat a pile of self-hosted posts
The most useful result for anyone who publishes is the placement test. Search Engine Journal describes paired vacation-destination posts across 5 topics. A post on a frequently cited source produced the first reference or planted detail in every case. The lesser-referenced site needed up to 20 postings in the best case, and 40 postings on a self-hosted WordPress site got zero references within seven days [2]. The abstract states the same idea in a sharper form: one article on a high-preference platform had greater citation impact than more than 20 matched low-preference posts [1].
| Test | Setup | Reported result |
|---|---|---|
| Paired vacation posts | Frequently cited source versus lesser-referenced site, 5 topics | Frequently cited source produced the first reference or planted detail in every case |
| Lesser-referenced site | Best case | Up to 20 postings needed |
| Self-hosted WordPress | 40 posts | Zero references within 7 days |
| Sohu volume test | 6 subjects, 1 to 20 posts | Total citations rose from 24 to 128 (association, not proven effect) |
| GEO vendor package | $14, 13 posts in about 28 minutes | One Doubao answer cited a post with a planted detail within an hour (single instance) |
What "high-preference" probably means mechanically
The paper frames AI search as a pipeline where platforms retrieve pages, filter sources, select citations and then generate the answer, and it argues the selection step can amplify source bias [1]. Here is how that plausibly plays out, with the caveat that these mechanisms are my interpretation and not claims from the paper.
- Crawl and index freshness. Large platforms such as Medium, YouTube or Reddit are crawled constantly. A new page on a small domain may not be discovered for days.
- Domain-level trust priors. If a ranking or filtering stage scores domains rather than individual pages, a new page inherits the score of its host. A fresh WordPress install has none to inherit.
- Retrieval overlap. AI search tools generate sub-queries and retrieve results from the same few ranking systems. Pages that already rank well for a query pattern get retrieved more often, and pages on trusted hosts rank quickly.
- Citation habits. The mapping step shows each tool has favorite sources. If Perplexity favors YouTube and ChatGPT favors Wikipedia, a post on a favored site starts with a built-in advantage in that tool specifically.
Notice how this lines up with what many creators already see in classic search. A video on a large channel gets indexed in hours, and the same description on a brand new site takes weeks. The paper shows that gap is at least as wide in AI answers. We covered the creator-side version of search-first publishing in our guide to search-first YouTube Shorts formats and in the post on how YouTube video descriptions rank in search.
The Sohu volume test, and why it is only an association
In a separate test on Sohu with 6 subjects and between 1 and 20 posts each, total citations across all ten tools rose from 24 to 128 as volume went up. ChatGPT never referenced these posts, and Google AI referenced them only for the three lowest-volume subjects. The authors describe this as an association and not a proven effect of post count [2].
Read that carefully. Volume correlated with more citations on one Chinese platform, but the two Western-leaning tools mostly ignored those posts, and the 40-post WordPress result shows volume alone does not rescue a weak host. Placement comes first, and repetition helps only once placement is right.
4) The $14 package and what it does and does not prove
The most headline-friendly result is the cheap one. The authors bought a Chinese GEO (generative engine optimization) posting package for $14. It delivered all 13 posts in about 28 minutes, and a Doubao answer cited one post containing a planted detail within an hour [1][2].
The authors present this as a single confirmed instance and not a success rate [2]. It shows that the pathway is real and cheap. It does not show that $14 buys reliable influence over real brand queries, and I would be wary of any vendor that cites this paper as proof their package works.
Why brands should care even if they never buy such a package
Competitors can. If a fabricated claim about your product, a distorted comparison, or an invented "alternative to X" listing gets planted on a high-preference platform, an AI tool may repeat it. The paper tested fictional topics only, so we do not know how strongly established brand facts resist this, and the authors note that their results may not generalize to real brands or products [2]. The sensible response to uncertainty is monitoring, which section 7 covers.
5) Where Google's May 2026 clarification fits
The tests ran in March and April. On May 15, 2026, Google clarified that its spam policies cover attempts to manipulate generative AI responses in Search [2]. Search Engine Roundtable reported that Google updated the leading paragraph of its spam policies, and that the changelog language says the Google Search spam policies also apply to generative AI responses in Google Search, including AI Overviews and AI Mode [3].
I checked Google's current spam policies page directly. Its definition of spam includes attempting to manipulate generative AI responses in Google Search, alongside the older language about deceiving users and manipulating Search ranking [4].
Two details to keep straight. Search Engine Roundtable's article is dated May 15, 2026, but the version I read does not state the changelog date itself, and it notes a Wayback Machine snapshot from May 13 with the earlier wording, so the exact edit date sits between those two [3]. I therefore use May 15 as the date Google's clarification was reported. Also, this is a clarification of existing policy and not a new rule set, and it applies to Google Search surfaces. It says nothing binding about ChatGPT, Perplexity or Grok, which are governed by their own terms.
Search Engine Journal also notes that Google's AI optimization guide says seeking inauthentic mentions is not as helpful as it might seem [2]. In plain terms, Google's stated position is that you should not manufacture mentions, and that doing so may count as spam.
The enforcement gap
Policy and detection are different things. The authors disclosed their findings to all ten platforms, and ChatGPT, Perplexity and Google AI acknowledged receipt [2]. The authors also warn that the exact rates may drift as the tools change, since the tests ran before Google's clarification [2]. Treat the specific percentages as a March and April 2026 snapshot.
6) What creators and brands should do (and what to avoid)
The research describes an attack surface, but the same facts tell legitimate publishers where effort pays off. The line I draw is simple: it is fine to put real, accurate work in front of the places AI tools already read, and it is not fine to fabricate claims, fake reviews, fake accounts or mass-produced posts intended to make a tool say something untrue.
Do: publish real work where AI tools already look
Because six to ten of each tool's top ten cited sources accepted ordinary user posts [2], a genuine write-up on one of those platforms is a legitimate way to be discoverable. Examples that stay on the right side of the line:
- A YouTube video with a full transcript, chapters and a descriptive description that answers one specific question well.
- A Medium or LinkedIn article that publishes your own original data, a real tutorial or a genuine case study, linking back to the canonical version on your site.
- A GitHub README or documentation page for a real tool you actually maintain.
- A real answer in a community where you disclose your affiliation.
If you make video, clips of a long video are a natural way to give one idea several citable surfaces. Miraflow's AI Clipping turns a long video into captioned vertical clips, and our walkthrough on turning a long video into viral Shorts automatically shows the workflow. Captions also give platforms more text to index.
Do: make your own site easy to cite and verify
The self-hosted WordPress result does not mean your own site is worthless. It means a new, low-authority host loses a race against a platform in a one-week window [2]. Your site is still where you control accuracy, so keep it as the source of record.
- Put the claim, the date, the author and the evidence near the top of the page.
- Use specific names and numbers, since the experiment's planted details were exactly how the researchers could trace reuse.
- Keep one canonical URL per fact so a tool that cites you cites the page you want.
- Check that your robots rules do not block the crawlers you want. OpenAI documents OAI-SearchBot as the agent used to surface sites in ChatGPT search, GPTBot as the crawler for training data, and ChatGPT-User as the agent that fetches pages when a user asks a question [5]. Perplexity documents PerplexityBot as its search indexer and Perplexity-User as the agent that fetches pages in response to a user question [6].
Do: publish original visuals and data other people can point to
Original charts, screenshots and datasets are hard to fake and easy to cite. If you create visuals for posts, Miraflow's AI Image Generator can produce featured images, and our blog featured image prompt templates show how to brief one well. For video, Text2Shorts turns a topic into a vertical video with a script you can edit before it renders, which keeps a human check in the loop.
Do not: manufacture citations
Skip the following, both for ethical reasons and because Google's policy now names generative AI manipulation explicitly [4]:
- Buying bulk posting packages whose purpose is to seed claims on many platforms.
- Planting fabricated facts, fake statistics or invented concepts to see whether a tool repeats them. The researchers did this under controlled conditions, disclosed to the platforms, and used fictional topics so no real person or product was harmed. A marketer doing it to a real market is a different act.
- Posting through sockpuppet accounts or hiding commercial relationships.
- Publishing negative claims about competitors that you cannot document.
There is also a purely practical reason. Platforms received the disclosure, and the tools will change. A strategy built on a loophole that was reported to ten vendors in 2026 has a short shelf life.
A short comparison by publisher type
- Small creator with a new site: put your best original material on one or two platforms the tools cite, and link back to your own pages. Expect days to weeks for a new domain to be picked up.
- Established brand: monitor first. You have the most to lose from a planted claim, and you probably already have strong coverage that resists a lone post.
- Researcher or journalist: your risk is citing an AI answer that itself rests on one planted post. Click through to sources, as the next section explains.
- Agency selling GEO services: ask what is being published, where, and whether it is true. A package that cannot answer that question is a liability for your client.
7) How to check whether AI tools are citing your content
You do not need a paid dashboard to start. Two cheap methods give you real evidence: server logs for AI crawler visits, and a repeatable question set whose answers you save and parse.
Method one: look for AI user agents in your logs
The agents documented by OpenAI and Perplexity are named above [5][6]. A user-initiated fetch such as ChatGPT-User or Perplexity-User in your log means someone asked a question and a tool visited your page, which is a stronger signal than an index crawl. Note that OpenAI says robots.txt rules may not apply to ChatGPT-User because the visit is user-initiated [5], and Perplexity says Perplexity-User generally ignores robots.txt for the same reason [6].
bash/code
# Count visits from AI-related user agents in an nginx or Apache access log.
# Agent names are from OpenAI's and Perplexity's crawler documentation.
for agent in OAI-SearchBot GPTBot ChatGPT-User PerplexityBot Perplexity-User; do
  printf "%-16s %s\n" "$agent" "$(grep -c "$agent" /var/log/nginx/access.log)"
done
# Pages fetched by a user-triggered agent (someone asked a question):
grep -E "ChatGPT-User|Perplexity-User" /var/log/nginx/access.log | awk '{print $7}' | sort | uniq -c | sort -rn | head -20
Method two: run the same questions weekly and log the citations
The paper's design is worth borrowing for good purposes: ask the same fixed questions on a schedule, and record which URLs each answer cites. You can paste or export answers from each tool into text files and run a small script over the folder. The script below makes no network calls. It extracts URLs from saved answers, tallies cited domains, and flags whether your own domains appear.
python/code
# citation_log.py: tally cited domains in saved AI answers. No network calls.
# Usage: python citation_log.py answers_folder yourdomain.com,otherdomain.com
import csv, re, sys
from collections import Counter
from pathlib import Path
from urllib.parse import urlparse

URL_RE = re.compile(r"https?://[^\s)\]>\"']+")

def domain(url):
    host = urlparse(url.rstrip(".,;")).netloc.lower()
    return host[4:] if host.startswith("www.") else host

def main(folder, mine):
    mine = {d.strip().lower() for d in mine.split(",") if d.strip()}
    totals, rows = Counter(), []
    for path in sorted(Path(folder).glob("*.txt")):
        urls = URL_RE.findall(path.read_text(encoding="utf-8", errors="ignore"))
        domains = [domain(u) for u in urls]
        totals.update(domains)
        hit = any(d == m or d.endswith("." + m) for d in domains for m in mine)
        rows.append((path.name, len(urls), hit))
    with open("citation_log.csv", "w", newline="", encoding="utf-8") as f:
        w = csv.writer(f)
        w.writerow(["file", "urls_cited", "mentions_my_domain"])
        w.writerows(rows)
    print("Top cited domains:")
    for d, n in totals.most_common(10):
        print(f"  {n:3d}  {d}")
    print(f"Answers citing my domains: {sum(1 for r in rows if r[2])} of {len(rows)}")

if __name__ == "__main__":
    if len(sys.argv) != 3:
        sys.exit("usage: python citation_log.py answers_folder domain1,domain2")
    main(sys.argv[1], sys.argv[2])
If you want a stricter test of whether a tool is quoting your page and not a copy, add a short, true, unique phrase to a genuine page, such as a named internal metric you really use, and search for that phrase in saved answers. This is the benign version of the researchers' planted markers: it uses only true content, and you control the page.
python/code
# marker_check.py: find a short, true, unique phrase from your own page in saved AI answers.
# Usage: python marker_check.py answers_folder "your unique phrase"
import sys
from pathlib import Path

folder, phrase = Path(sys.argv[1]), sys.argv[2].lower()
hits = [p.name for p in sorted(folder.glob("*.txt"))
        if phrase in p.read_text(encoding="utf-8", errors="ignore").lower()]
print(f"{len(hits)} answer file(s) repeat the phrase")
for name in hits:
    print(" ", name)
How to design the question set
- Write 15 to 30 questions a real customer would ask, covering your brand, your category and your competitors.
- Keep wording fixed. Changing a question changes the retrieval.
- Run the set once a week on each tool you care about, and save the full answer text and the cited links.
- Record the date. The paper's results depend on timing, and the authors expect rates to drift.
- Review changes in who gets cited, not just whether you appear. A competitor suddenly cited on a question where you used to appear is the actual alert.
8) What this means for how answer engines pick sources
Pulling the findings together, the picture is a pipeline with a weak point in the middle.
- Retrieval finds pages for the question, often through several sub-queries.
- Filtering drops pages the system distrusts.
- Citation selection chooses which of the survivors to show.
- Generation writes an answer, which may or may not repeat the source's specific claims.
The authors argue that the selection step amplifies bias toward a small set of domains, and that this turns ordinary posting into an indirect route into citations and answer text [1]. The per-tool numbers add a refinement: tools differ in how much they trust what they cite. Grok repeated planted details in 53% of its answers while Perplexity repeated none, even though both linked to the posts often [2]. So the ability to get a link and the ability to get your wording repeated are separate properties, and they vary by product.
Likely next changes
Predictions here are my own judgment, not findings. Expect tools to add host-independent quality checks, such as requiring corroboration from a second independent source before treating a claim from a new post as fact, and to weigh account age and history on user-post platforms. Expect fewer fictional-concept successes and more subtle cases, such as claims that blend into a crowded topic. That is why the keyboard result, where established coverage resisted the posts, is arguably the more relevant signal for real brands.
Limits of this paper you should keep in mind
- All topics were fictional, so results may not carry over to real brands or products [2].
- Topic, competition and question type varied together, so the paper cannot say which one explains differences [2].
- The "Google AI" tool is linked to Google's general AI site in the paper without specifying which product was tested [2].
- The Sohu volume result is an association, and the $14 package is a single instance [2].
- The tests ran in March and April, before Google's May clarification, and rates may have shifted since.
9) Common mistakes when reacting to this research
Treating one week as a steady state. The paper measures citation within seven days. It says nothing about whether the posts stayed cited, and tool behavior changes.
Concluding that your own site is useless. The 40-post WordPress result is about a new, low-authority host in a short window. It argues for publishing in more than one place, not abandoning your domain.
Copying the experiment on real topics. Planting false claims about a real brand or person can harm people and may violate platform rules and Google's spam policy [4].
Quoting percentages without the denominator. Grok's 30 of 32 and ChatGPT's 7 of 20 are small samples. Report the counts alongside the percentages.
Ignoring the second kind of risk. Many readers will think about how to get cited and forget the reverse: an AI answer you rely on may be resting on a single planted post. Click through and check who wrote it.
Optimizing for tools you cannot measure. Without logs or a saved question set, you cannot tell whether a change worked. Start measuring before you start changing.
10) Related reading on security and AI answers
If this research interests you, our explainers on adjacent security topics cover how fragile AI systems can be when they trust inputs they should not. See ToolHazard on indirect prompt injection, the PaperCut AI agent attack explainer and the roundup of AI agent sandbox escape incidents. For creators following how search itself is changing, Ask YouTube conversational search, Instagram and Google Search Console for Reels SEO and TikTok SEO in 2026 are good companions. On the advertising side, AI Overviews and shopping impressions shows how AI answers affect paid search.
You can also explore everything Miraflow offers from the Miraflow home page, or turn a blog post into a short video with our guide to turning a blog post into a viral YouTube Short.
Frequently Asked Questions
What is AI search poisoning?
It is a label for planting content on public sites so that AI search tools cite it or repeat it. The Fudan paper does not require that exact phrase, but its experiments show the mechanism: ordinary posts on preferred platforms changed AI search outputs, with 8 of 10 platforms citing a fabricated concept within seven days [1].
Which AI tools cited the made-up concept?
Eight of the ten tools did, including all four English-web tools tested: ChatGPT, Perplexity, Grok and Google AI [2]. The other six tools tested were Chinese-web tools, including Doubao and DeepSeek.
Does this mean AI answers about real brands can be easily manipulated?
Not necessarily. The topics were fictional, so the paper does not show how well established brand facts resist a planted post, and the authors note that the results may not generalize to real brands or products [2]. Monitoring is still sensible.
Why did posts on Medium or YouTube work better than a self-hosted WordPress site?
The paired test found that a post on a frequently cited source produced the first reference in every case, while 40 posts on a self-hosted WordPress site got zero references in seven days [2]. The paper does not give a single mechanism, but the abstract argues that the citation selection step is biased toward a small set of domains [1].
Is GEO manipulation against Google's rules?
Google's spam policies now state that attempting to manipulate generative AI responses in Google Search counts as spam [4]. Google clarified this in May 2026 [3]. Other AI tools follow their own policies.
Is it okay to publish on Medium or LinkedIn to get cited?
Yes, when the content is real, accurate and disclosed as yours. The problem is fabricated claims, fake accounts and bulk seeding, not publishing on well-trusted platforms.
How can I tell if ChatGPT or Perplexity visits my site?
Check your server logs for the documented user agents: OAI-SearchBot, GPTBot and ChatGPT-User for OpenAI [5], and PerplexityBot and Perplexity-User for Perplexity [6]. Also keep a weekly saved question set.
Will these results still hold next month?
Probably not exactly. The tests ran in March and April, the authors disclosed to all ten platforms, and they say rates may drift as tools change [2].
Conclusion
The Fudan result is easy to summarize and hard to dismiss: a fabricated concept reached AI answers in a week on 8 of 10 tools, one article on a heavily cited platform outperformed more than 20 posts elsewhere, and a $14 package produced 13 posts in about half an hour [1][2]. It also has real limits, because every topic was fictional and the tests predate Google's May clarification.
For publishers the sensible response is calm and practical. Put real, specific, verifiable work where AI tools already look, keep your own site as the source of record, avoid manufactured mentions, and measure citations with logs and a fixed question set so you notice changes early. If you create video or images to support that work, Miraflow's Text2Shorts, AI Clipping and AI Image Generator can help you produce them quickly, and the Miraflow home page lists the rest.
References
- [1] Qi Liu, Geng Hong, Xinyang Zhang, Pei Chen, Yutong Li, Min Yang. From Public Posts to AI-Search Citations: Measuring the Fragility of AI Search. arXiv:2610.11932, submitted October 8, 2026 (cs.CR).
- [2] Matt G. Southern. AI Search Tools Cited A Made-Up Concept Within A Week, Paper Finds. Search Engine Journal, October 19, 2026.
- [3] Google: Spam Policies Apply To AI Responses (AI Overviews & AI Mode). Search Engine Roundtable, May 15, 2026.
- [4] Spam policies for Google web search. Google Search Central.
- [5] Overview of OpenAI crawlers. OpenAI documentation.
- [6] Perplexity crawlers. Perplexity documentation.